{
 "cells": [
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "# 动手学 RLHF\n",
    "> 本实验手册翻译并整合了网络资料 [blog](https://newfacade.github.io/notes-on-reinforcement-learning/17-ppo-trl.html) & [trl examples](https://github.com/huggingface/trl/blob/main/examples/notebooks/gpt2-sentiment.ipynb)\n",
    "\n",
    "复现实验配置：单卡 NVDIA A800-SXM4-80GB 占用 10097MiB，训练耗时 35min19s。\n",
    "\n",
    "## PPO 如何运作\n",
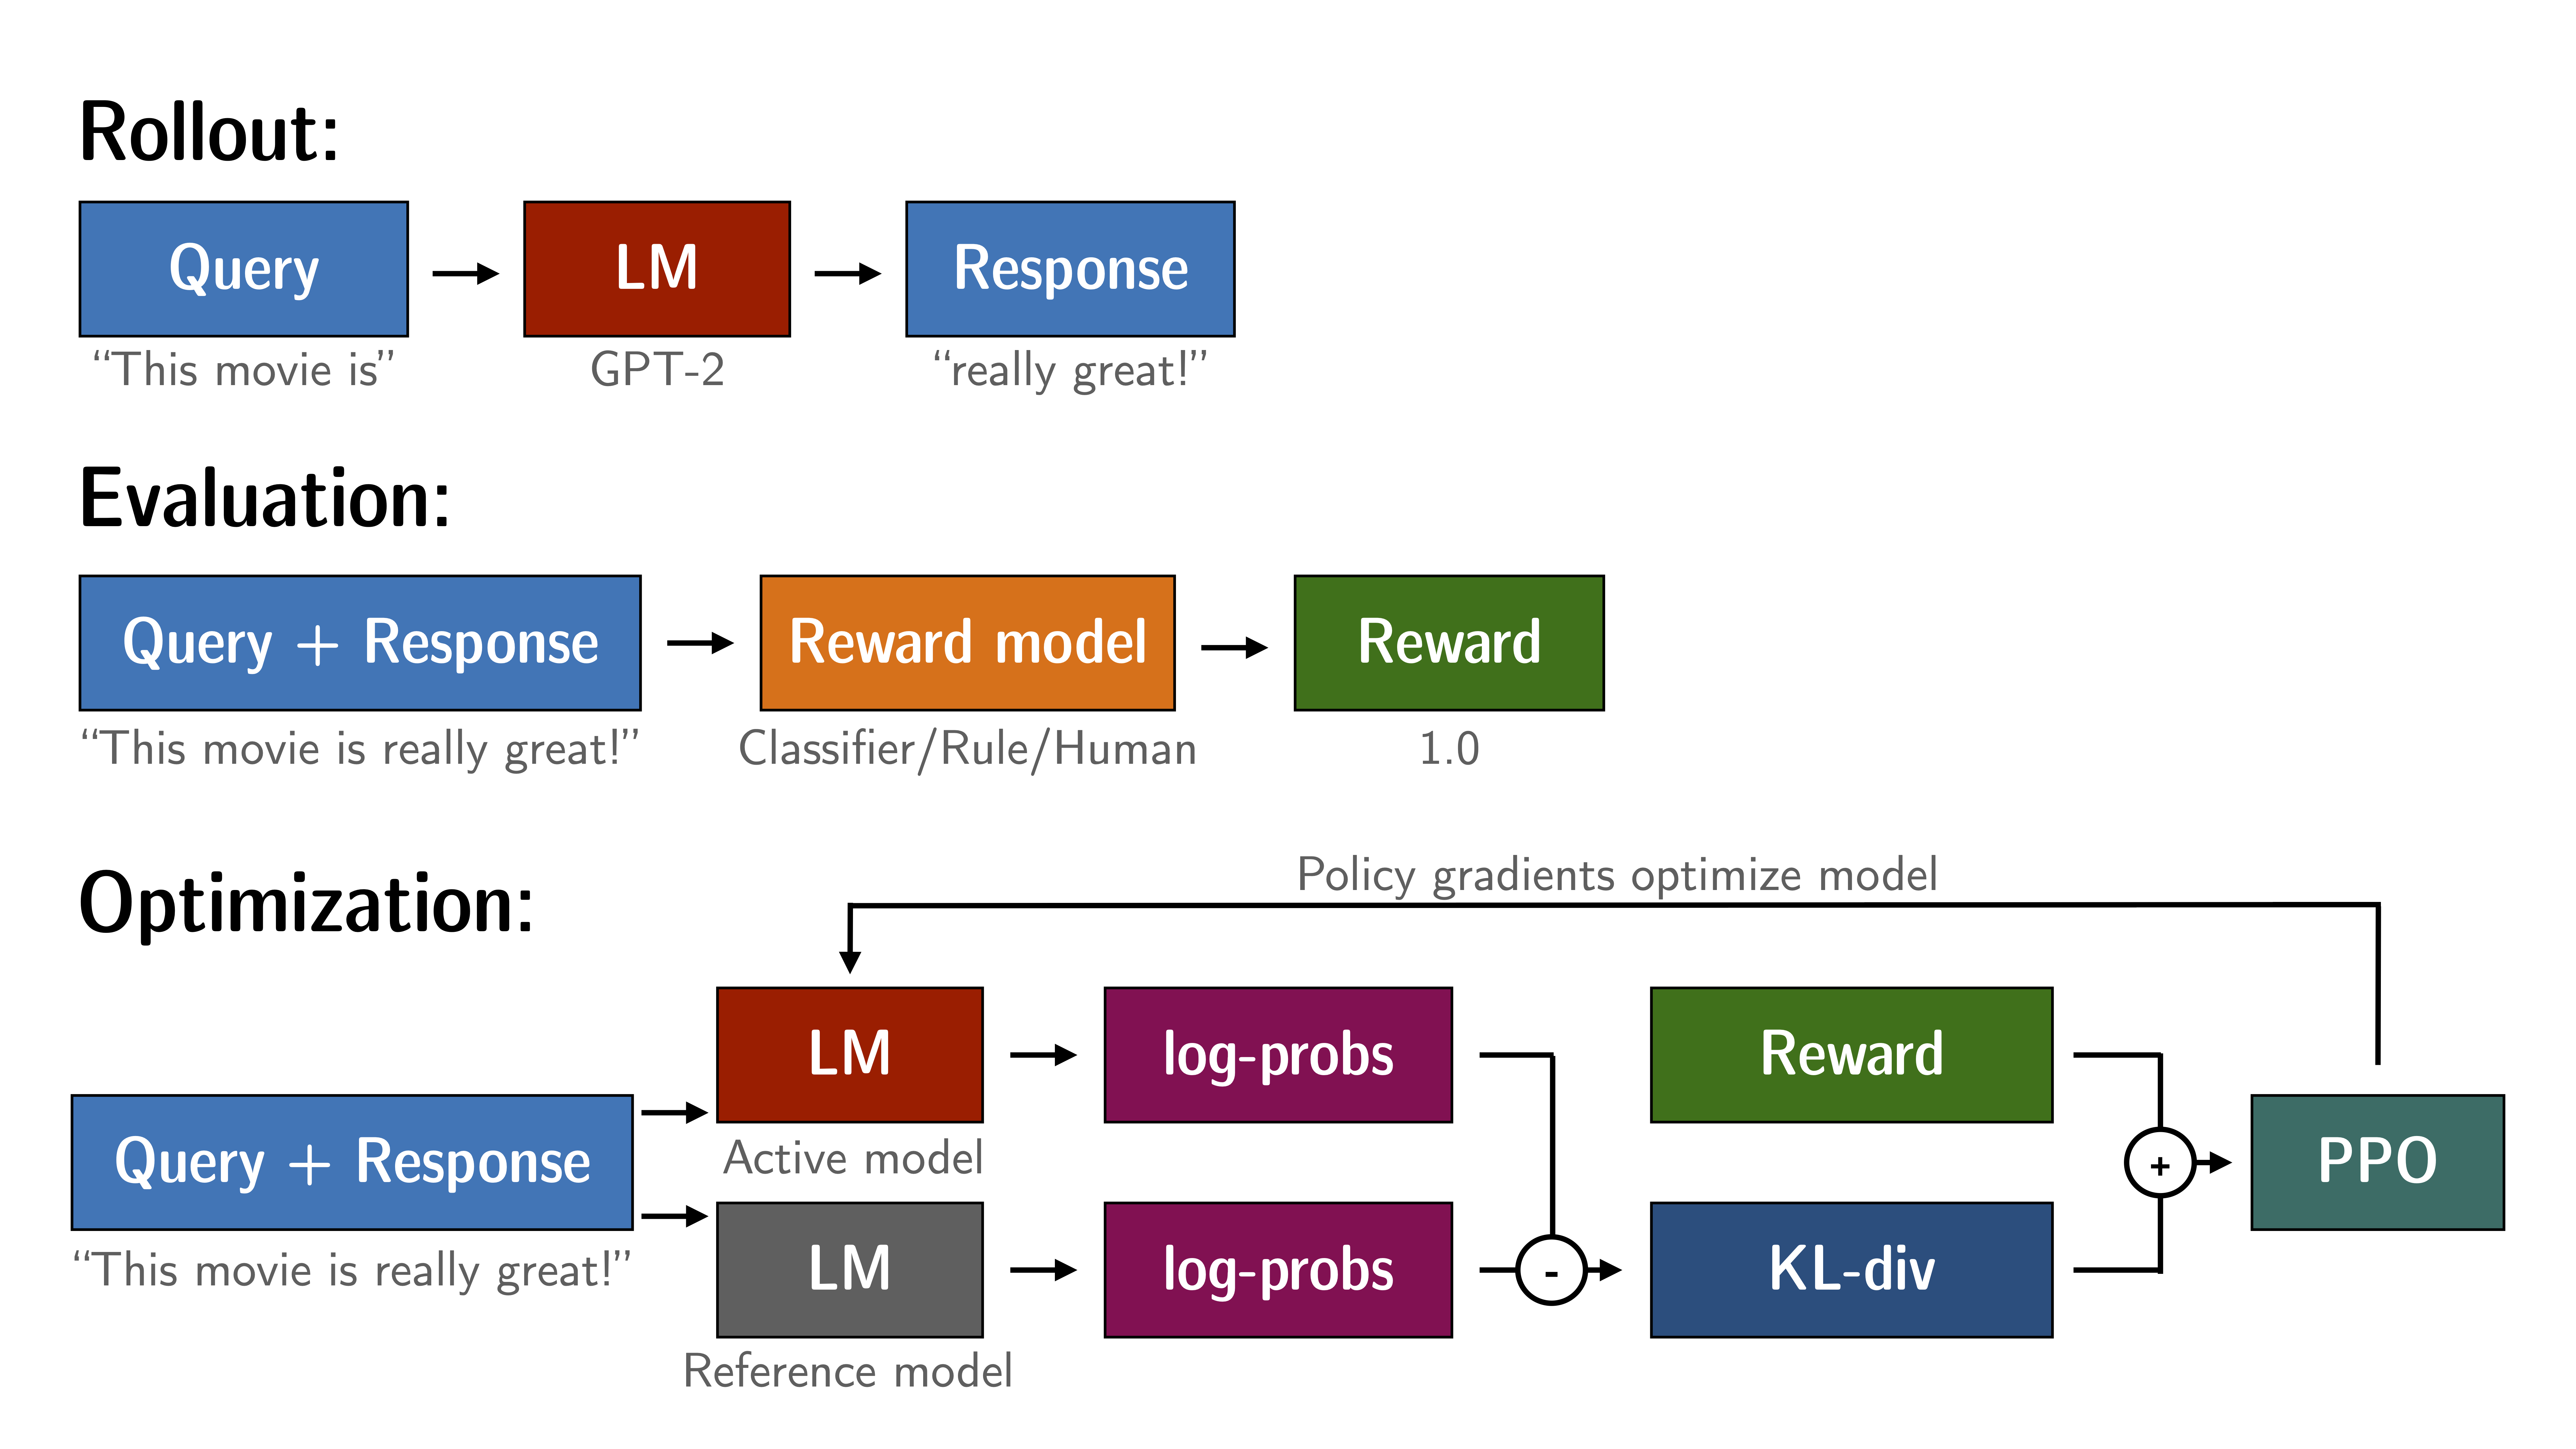
    "1. Rollout：语言模型根据 query 生成响应。\n",
    "2. Evaluation：查询和响应使用函数、模型、人工反馈或它们的某种组合进行评估。此过程应为每个查询/响应对生成一个**标量值**。\n",
    "3. Optimization：在优化步骤中，查询/响应对用于计算序列中标记的对数概率。这是通过训练的模型和参考模型完成的。两个输出之间的 KL 散度用作额外的奖励信号，以确保生成的响应不会偏离参考语言模型太远。然后使用 PPO 训练主动语言模型。\n",
    "<div style=\"text-align: center\">\n",
    "<img src='figs/trl1.png' width='600'>\n",
    "<p style=\"text-align: center;\"> <b>图:</b> PPO 流程图 </p>\n",
    "</div>"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "# 微调 GPT-2 以生成积极评论  \n",
    "> 通过使用 BERT 情感分类器作为奖励函数，优化 GPT-2 以生成积极的 IMDB 电影评论。"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
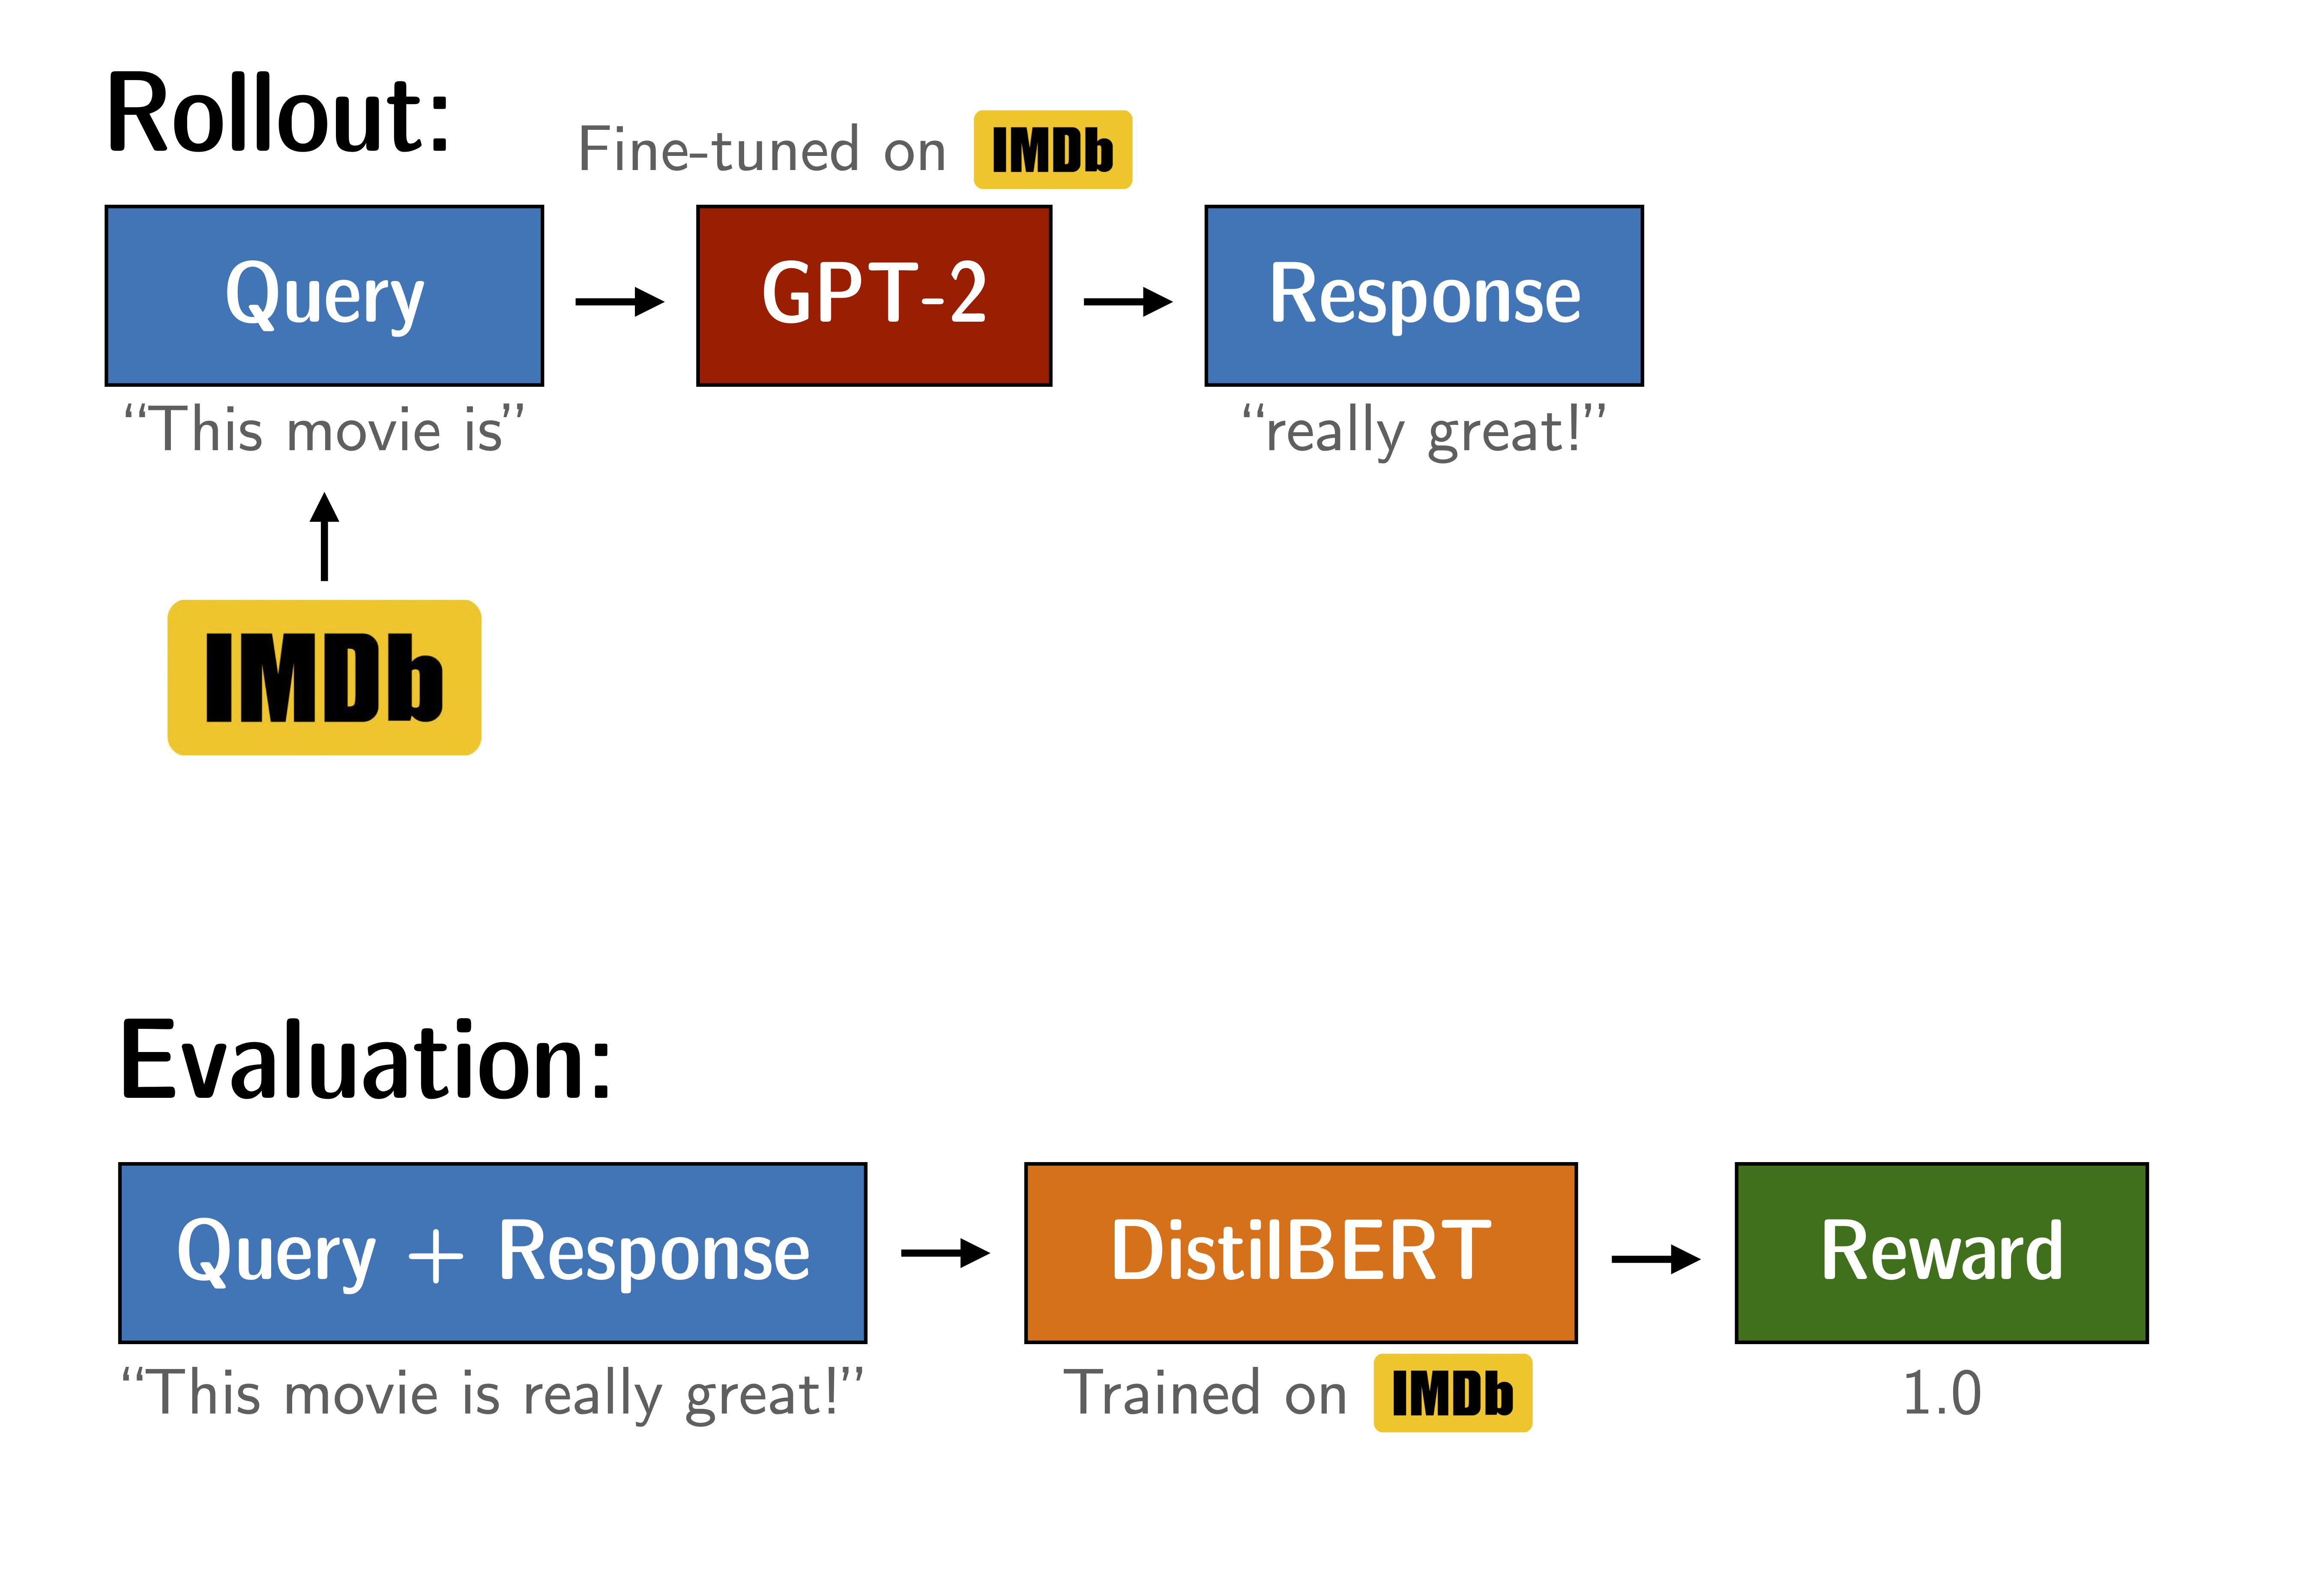
    "<div style=\"text-align: center\">\n",
    "<img src='figs/gpt2_bert_training.png' width='600'>\n",
    "<p style=\"text-align: center;\"> <b>图：</b> 微调 GPT-2 的实验设置</p>\n",
    "</div>\n",
    "\n",
    "我们微调 GPT-2 以基于 IMDB 数据集生成积极的电影评论。该模型会接收真实评论的开头部分，并需要生成积极的后续内容。为了奖励积极的后续内容，我们使用 BERT 分类器来分析生成句子的情感，并将分类器的输出作为 PPO 训练的奖励信号。"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "## 实验设置"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 下载模型和数据\n",
    "数据集\n",
    "```bash\n",
    "export HF_ENDPOINT=https://hf-mirror.com; huggingface-cli download --resume-download stanfordnlp/imdb --local-dir dataset/imdb --repo-type dataset\n",
    "```\n",
    "参考模型\n",
    "```bash\n",
    "export HF_ENDPOINT=https://hf-mirror.com; huggingface-cli download --resume-download lvwerra/gpt2-imdb --local-dir model/gpt2-imdb\n",
    "```\n",
    "奖励模型\n",
    "```bash\n",
    "export HF_ENDPOINT=https://hf-mirror.com; huggingface-cli download --resume-download lvwerra/distilbert-imdb --local-dir model/distilbert-imdb\n",
    "```"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 导入依赖项"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "metadata": {},
   "outputs": [],
   "source": [
    "# %pip install -r requirements.txt\n",
    "# import os\n",
    "# os.environ['CUDA_VISIBLE_DEVICES'] = '7'"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 2,
   "metadata": {},
   "outputs": [],
   "source": [
    "import torch\n",
    "from tqdm import tqdm\n",
    "import pandas as pd\n",
    "\n",
    "tqdm.pandas()\n",
    "\n",
    "from transformers import pipeline, AutoTokenizer\n",
    "from datasets import load_dataset\n",
    "\n",
    "from trl import PPOTrainer, PPOConfig, AutoModelForCausalLMWithValueHead\n",
    "from trl.core import LengthSampler"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 配置"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 3,
   "metadata": {},
   "outputs": [],
   "source": [
    "config = PPOConfig(\n",
    "    model_name=\"model/gpt2-imdb\",\n",
    "    learning_rate=1.41e-5,\n",
    "    log_with=\"wandb\",\n",
    ")\n",
    "\n",
    "sent_kwargs = {\"top_k\": None, \"function_to_apply\": \"none\", \"batch_size\": 16}"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "metadata": {},
   "outputs": [],
   "source": [
    "import wandb\n",
    "\n",
    "wandb.init()"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "你可以看到我们加载了一个名为 `gpt2_imdb` 的 GPT-2 模型。该模型在 IMDB 数据集上额外微调了 1 个 epoch，使用的是 Hugging Face 的[脚本](https://github.com/huggingface/transformers/blob/main/examples/legacy/run_language_modeling.py)（无特殊设置）。其余参数主要取自原始论文《[Fine-Tuning Language Models from Human Preferences](https://huggingface.co/papers/1909.08593)》。该模型以及 BERT 模型均可在 Hugging Face 的模型库中获取，具体链接在[这里](https://huggingface.co/models)。"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "## 加载数据和模型"
   ]
  },
  {
   "attachments": {},
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 加载 IMDB 数据集  \n",
    "IMDB 数据集包含了 50,000 条电影评论，并标注了“积极”/“消极”的情感反馈。我们将 IMDB 数据集加载到一个 DataFrame 中，并筛选出至少 200 个字符的评论。然后，我们对每条文本进行分词，并使用 `LengthSampler` 将其随机截断为指定长度。"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 5,
   "metadata": {},
   "outputs": [],
   "source": [
    "def build_dataset(\n",
    "    config,\n",
    "    dataset_name=\"dataset/imdb\",\n",
    "    input_min_text_length=2,\n",
    "    input_max_text_length=8,\n",
    "):\n",
    "    \"\"\"\n",
    "    Build dataset for training. This builds the dataset from `load_dataset`, one should\n",
    "    customize this function to train the model on its own dataset.\n",
    "\n",
    "    Args:\n",
    "        dataset_name (`str`):\n",
    "            The name of the dataset to be loaded.\n",
    "\n",
    "    Returns:\n",
    "        dataloader (`torch.utils.data.DataLoader`):\n",
    "            The dataloader for the dataset.\n",
    "    \"\"\"\n",
    "    tokenizer = AutoTokenizer.from_pretrained(config.model_name)\n",
    "    tokenizer.pad_token = tokenizer.eos_token\n",
    "    # load imdb with datasets\n",
    "    ds = load_dataset(dataset_name, split=\"train\")\n",
    "    ds = ds.rename_columns({\"text\": \"review\"})\n",
    "    ds = ds.filter(lambda x: len(x[\"review\"]) > 200, batched=False)\n",
    "\n",
    "    input_size = LengthSampler(input_min_text_length, input_max_text_length)\n",
    "\n",
    "    def tokenize(sample):\n",
    "        sample[\"input_ids\"] = tokenizer.encode(sample[\"review\"])[: input_size()]\n",
    "        sample[\"query\"] = tokenizer.decode(sample[\"input_ids\"])\n",
    "        return sample\n",
    "\n",
    "    ds = ds.map(tokenize, batched=False)\n",
    "    ds.set_format(type=\"torch\")\n",
    "    return ds"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 6,
   "metadata": {},
   "outputs": [],
   "source": [
    "dataset = build_dataset(config)\n",
    "\n",
    "\n",
    "def collator(data):\n",
    "    return dict((key, [d[key] for d in data]) for key in data[0])"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 加载预训练的 GPT2 语言模型\n",
    "我们加载带有值头（value head）的 GPT2 模型和分词器。我们加载了两次模型；第一个模型用于优化，而第二个模型作为参考，用于计算与初始点的 KL 散度（KL-divergence）。这在 PPO 训练中作为额外的奖励信号，以确保优化后的模型不会偏离原始语言模型太远。"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 7,
   "metadata": {},
   "outputs": [],
   "source": [
    "model = AutoModelForCausalLMWithValueHead.from_pretrained(config.model_name)\n",
    "ref_model = AutoModelForCausalLMWithValueHead.from_pretrained(config.model_name)\n",
    "tokenizer = AutoTokenizer.from_pretrained(config.model_name)\n",
    "\n",
    "tokenizer.pad_token = tokenizer.eos_token"
   ]
  },
  {
   "attachments": {},
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 初始化 PPOTrainer  \n",
    "`PPOTrainer` 负责后续的设备分配和优化："
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 8,
   "metadata": {},
   "outputs": [
    {
     "data": {
      "text/html": [
       "Finishing previous runs because reinit is set to 'default'."
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [
       " View run <strong style=\"color:#cdcd00\">comic-snowball-1</strong> at: <a href='https://wandb.ai/ai-detective/uncategorized/runs/rv0dl6cg' target=\"_blank\">https://wandb.ai/ai-detective/uncategorized/runs/rv0dl6cg</a><br> View project at: <a href='https://wandb.ai/ai-detective/uncategorized' target=\"_blank\">https://wandb.ai/ai-detective/uncategorized</a><br>Synced 5 W&B file(s), 0 media file(s), 0 artifact file(s) and 0 other file(s)"
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [
       "Find logs at: <code>./wandb/run-20250512_200154-rv0dl6cg/logs</code>"
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [
       "creating run (0.1s)"
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [
       "Tracking run with wandb version 0.19.11"
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [
       "Run data is saved locally in <code>/data1/home/donglz/codespace/RLHF/wandb/run-20250512_200308-qflpjm91</code>"
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [
       "Syncing run <strong><a href='https://wandb.ai/ai-detective/trl/runs/qflpjm91' target=\"_blank\">good-haze-1</a></strong> to <a href='https://wandb.ai/ai-detective/trl' target=\"_blank\">Weights & Biases</a> (<a href='https://wandb.me/developer-guide' target=\"_blank\">docs</a>)<br>"
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [
       " View project at <a href='https://wandb.ai/ai-detective/trl' target=\"_blank\">https://wandb.ai/ai-detective/trl</a>"
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "data": {
      "text/html": [
       " View run at <a href='https://wandb.ai/ai-detective/trl/runs/qflpjm91' target=\"_blank\">https://wandb.ai/ai-detective/trl/runs/qflpjm91</a>"
      ],
      "text/plain": [
       "<IPython.core.display.HTML object>"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    }
   ],
   "source": [
    "ppo_trainer = PPOTrainer(\n",
    "    config, model, ref_model, tokenizer, dataset=dataset, data_collator=collator\n",
    ")"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 加载 BERT 分类器  \n",
    "我们加载了一个在 IMDB 数据集上微调过的 BERT 分类器。"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 9,
   "metadata": {},
   "outputs": [
    {
     "name": "stderr",
     "output_type": "stream",
     "text": [
      "Device set to use cuda:0\n"
     ]
    }
   ],
   "source": [
    "device = ppo_trainer.accelerator.device\n",
    "if ppo_trainer.accelerator.num_processes == 1:\n",
    "    device = 0 if torch.cuda.is_available() else \"cpu\"  # to avoid a `pipeline` bug\n",
    "sentiment_pipe = pipeline(\n",
    "    \"sentiment-analysis\", model=\"model/distilbert-imdb\", device=device\n",
    ")"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "模型输出的是负面类和正面类的 logits。我们将使用正面类的 logits 作为语言模型的奖励信号。"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 10,
   "metadata": {},
   "outputs": [
    {
     "data": {
      "text/plain": [
       "[{'label': 'NEGATIVE', 'score': 2.3350484371185303},\n",
       " {'label': 'POSITIVE', 'score': -2.726576089859009}]"
      ]
     },
     "execution_count": 10,
     "metadata": {},
     "output_type": "execute_result"
    }
   ],
   "source": [
    "text = \"this movie was really bad!!\"\n",
    "sentiment_pipe(text, **sent_kwargs)"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 11,
   "metadata": {},
   "outputs": [
    {
     "data": {
      "text/plain": [
       "[{'label': 'POSITIVE', 'score': 2.557040214538574},\n",
       " {'label': 'NEGATIVE', 'score': -2.294790267944336}]"
      ]
     },
     "execution_count": 11,
     "metadata": {},
     "output_type": "execute_result"
    }
   ],
   "source": [
    "text = \"this movie was really good!!\"\n",
    "sentiment_pipe(text, **sent_kwargs)"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 生成设置  \n",
    "对于响应生成，我们仅使用采样方法，并确保关闭 top-k 和核采样（nucleus sampling），同时设置一个最小长度。"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 12,
   "metadata": {},
   "outputs": [],
   "source": [
    "gen_kwargs = {\n",
    "    \"min_length\": -1,\n",
    "    \"top_k\": 0.0,\n",
    "    \"top_p\": 1.0,\n",
    "    \"do_sample\": True,\n",
    "    \"pad_token_id\": tokenizer.eos_token_id,\n",
    "}"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "## 优化模型"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "### 训练循环"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "训练循环包括以下主要步骤：\n",
    "1. 从策略网络（GPT-2）中获取查询响应  \n",
    "2. 从 BERT 中获取查询/响应的情感  \n",
    "3. 使用 PPO 优化策略，利用（查询、响应、奖励）三元组  \n",
    "<!-- **训练时间**  \n",
    "在上述指定的设置下，此步骤在 V100 GPU 上需要 **约 2 小时**。 -->"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 13,
   "metadata": {},
   "outputs": [
    {
     "name": "stderr",
     "output_type": "stream",
     "text": [
      "  0%|          | 0/194 [00:00<?, ?it/s]The attention mask is not set and cannot be inferred from input because pad token is same as eos token. As a consequence, you may observe unexpected behavior. Please pass your input's `attention_mask` to obtain reliable results.\n",
      "  4%|▍         | 8/194 [01:23<32:18, 10.42s/it]You seem to be using the pipelines sequentially on GPU. In order to maximize efficiency please use a dataset\n",
      "100%|██████████| 194/194 [35:19<00:00, 10.92s/it]\n"
     ]
    }
   ],
   "source": [
    "output_min_length = 4\n",
    "output_max_length = 16\n",
    "output_length_sampler = LengthSampler(output_min_length, output_max_length)\n",
    "\n",
    "\n",
    "generation_kwargs = {\n",
    "    \"min_length\": -1,\n",
    "    \"top_k\": 0.0,\n",
    "    \"top_p\": 1.0,\n",
    "    \"do_sample\": True,\n",
    "    \"pad_token_id\": tokenizer.eos_token_id,\n",
    "}\n",
    "\n",
    "\n",
    "for epoch, batch in enumerate(tqdm(ppo_trainer.dataloader)):\n",
    "    query_tensors = batch[\"input_ids\"]\n",
    "\n",
    "    #### Get response from gpt2\n",
    "    response_tensors = []\n",
    "    for query in query_tensors:\n",
    "        gen_len = output_length_sampler()\n",
    "        generation_kwargs[\"max_new_tokens\"] = gen_len\n",
    "        query_response = ppo_trainer.generate(query, **generation_kwargs).squeeze()\n",
    "        response_len = len(query_response) - len(query)\n",
    "        response_tensors.append(query_response[-response_len:])\n",
    "    batch[\"response\"] = [tokenizer.decode(r.squeeze()) for r in response_tensors]\n",
    "\n",
    "    #### Compute sentiment score\n",
    "    texts = [q + r for q, r in zip(batch[\"query\"], batch[\"response\"])]\n",
    "    pipe_outputs = sentiment_pipe(texts, **sent_kwargs)\n",
    "    positive_scores = [\n",
    "        item[\"score\"]\n",
    "        for output in pipe_outputs\n",
    "        for item in output\n",
    "        if item[\"label\"] == \"POSITIVE\"\n",
    "    ]\n",
    "    rewards = [torch.tensor(score) for score in positive_scores]\n",
    "\n",
    "    #### Run PPO step\n",
    "    stats = ppo_trainer.step(query_tensors, response_tensors, rewards)\n",
    "    ppo_trainer.log_stats(stats, batch, rewards)"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
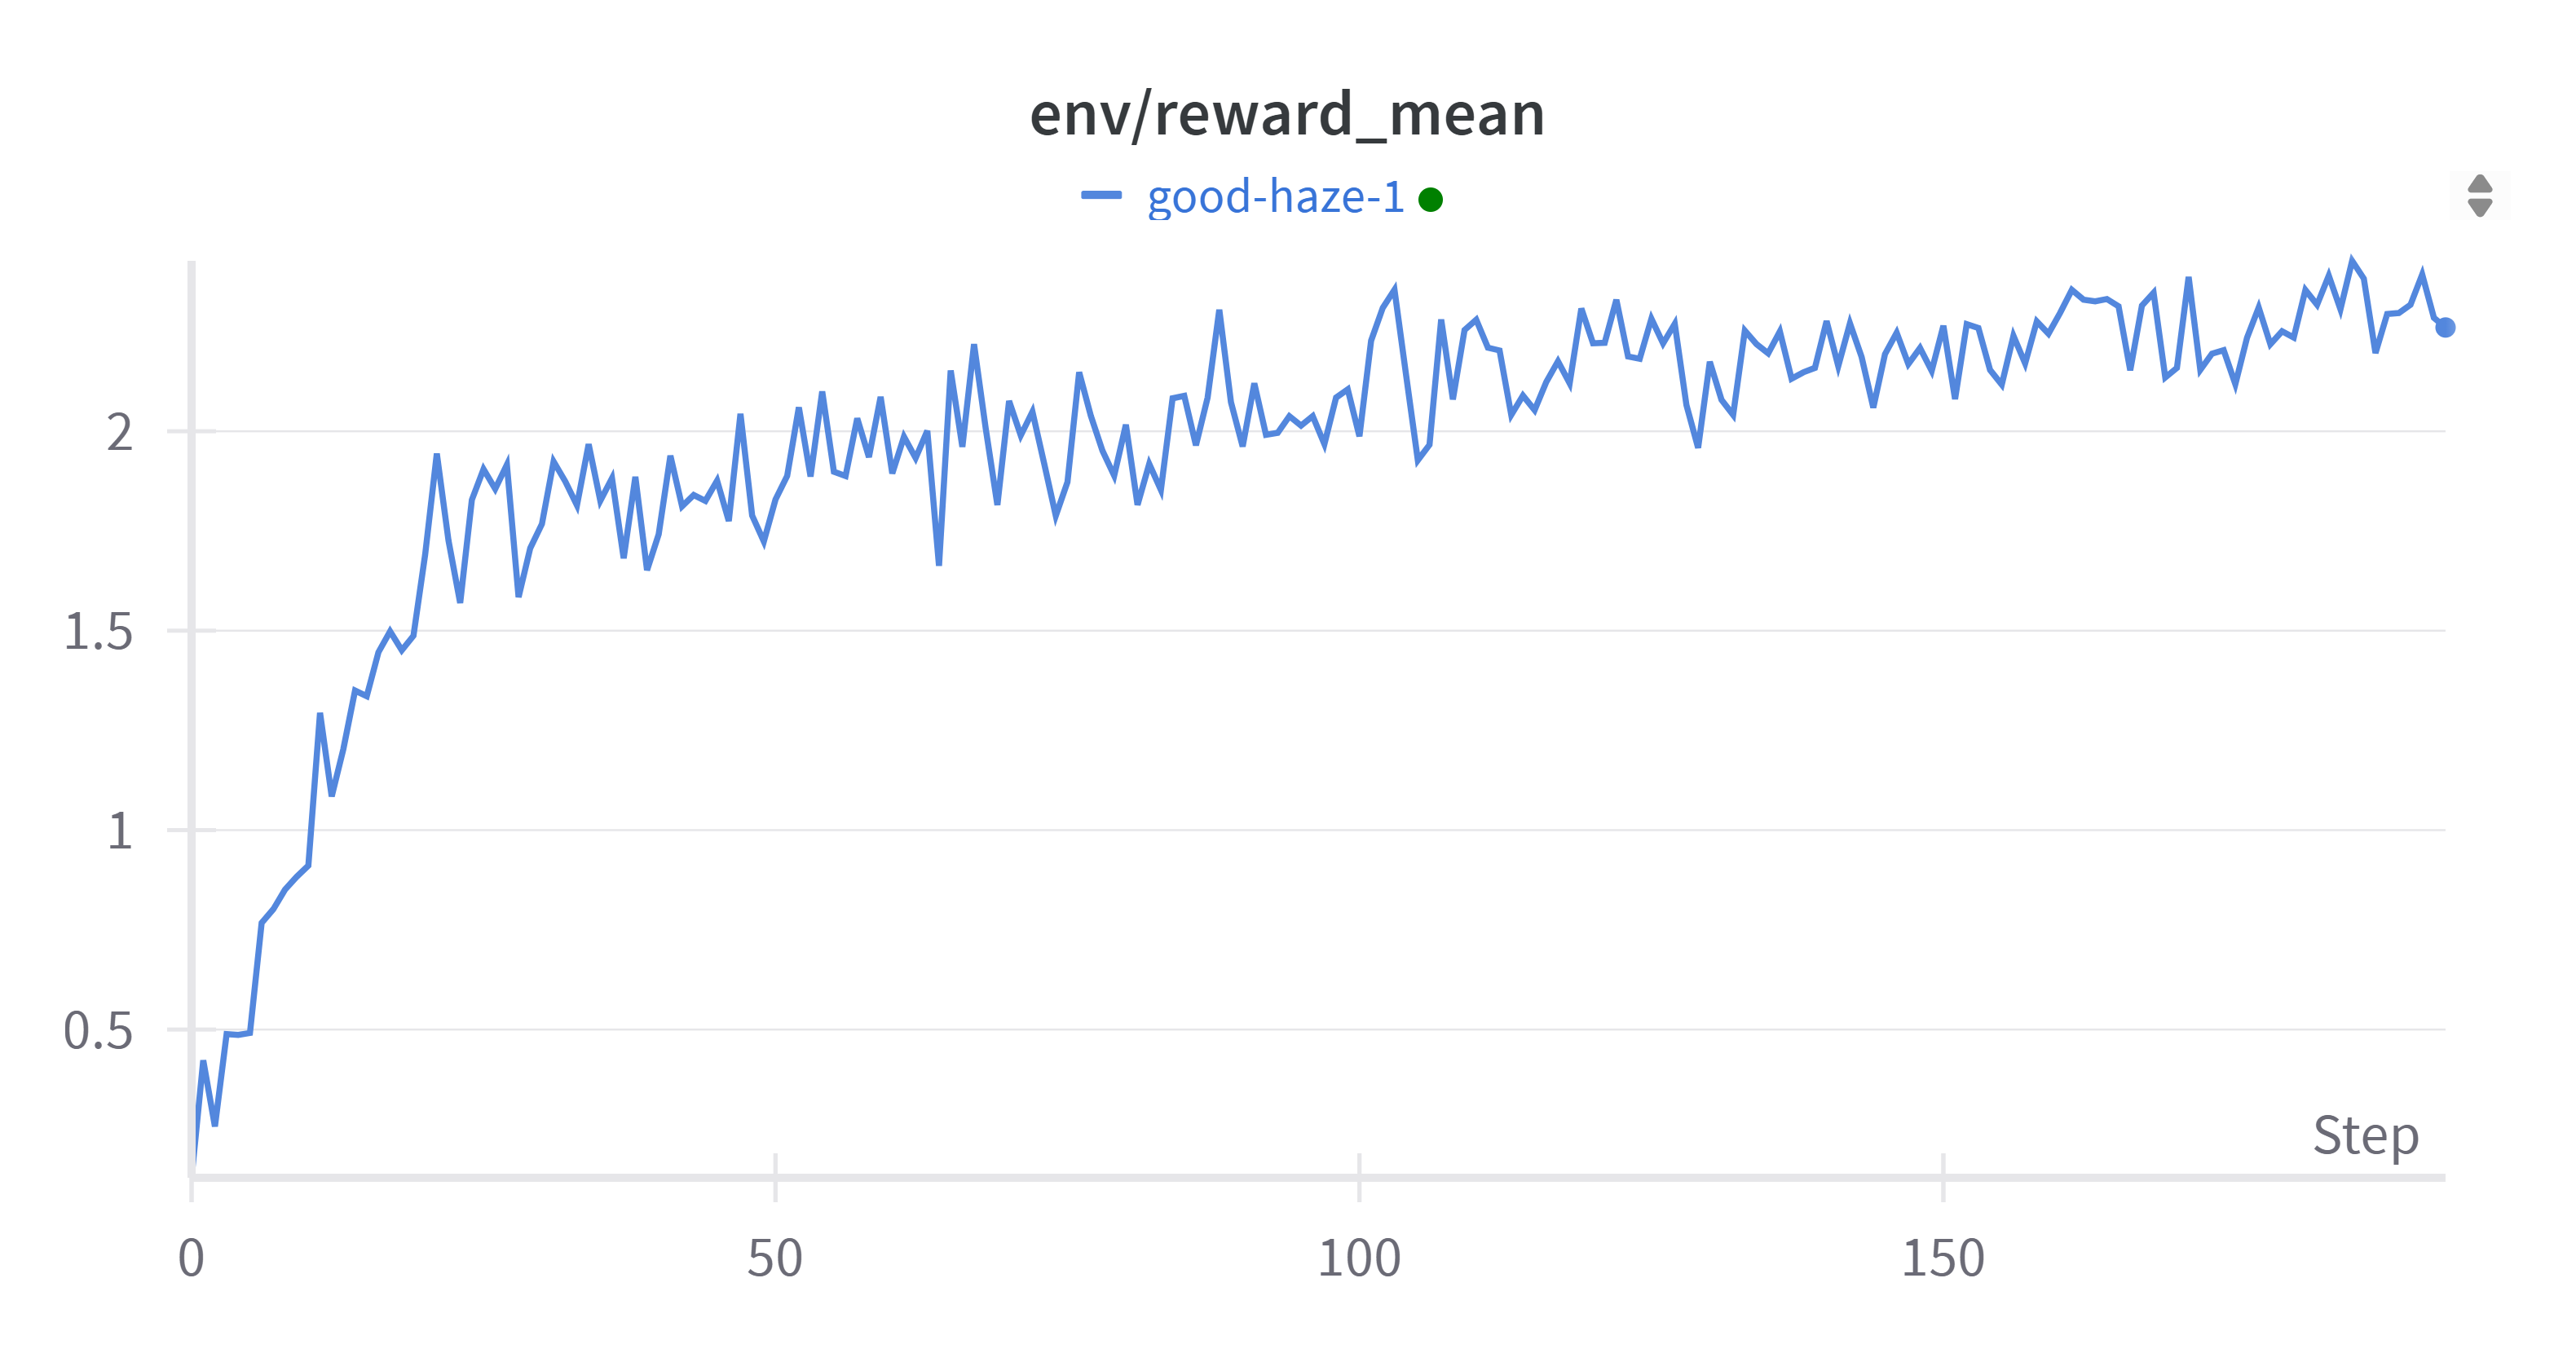
    "### 训练进展  \n",
    "如果你正在使用 Weights & Biases 跟踪训练进展，你应该会看到类似于下图的曲线。查看 wandb.ai 上的交互式示例报告：[链接](https://wandb.ai/huggingface/trl/runs/w9l3110g)。  \n",
    "<div style=\"text-align: center\">\n",
    "<img src='figs/gpt2_tuning_progress.png' width='800'>\n",
    "<p style=\"text-align: center;\"> <b>图：</b> 训练期间奖励均值的演变 </p>\n",
    "</div>  \n",
    "可以观察到，经过几次优化步骤后，模型开始生成更积极的输出。  \n",
    "\n",
    "<!-- > 注意：如果研究 KL 散度，可能会发现此时模型尚未收敛到目标 KL 散度。要达到目标需要更长的训练时间或更高的初始系数。 -->"
   ]
  },
  {
   "attachments": {},
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "## 模型检查  \n",
    "让我们从 IMDB 数据集中检查一些示例。我们可以使用 `ref_model` 来比较优化后的模型 `model` 与优化前的模型。"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 14,
   "metadata": {},
   "outputs": [
    {
     "data": {
      "text/html": [
       "<div>\n",
       "<style scoped>\n",
       "    .dataframe tbody tr th:only-of-type {\n",
       "        vertical-align: middle;\n",
       "    }\n",
       "\n",
       "    .dataframe tbody tr th {\n",
       "        vertical-align: top;\n",
       "    }\n",
       "\n",
       "    .dataframe thead th {\n",
       "        text-align: right;\n",
       "    }\n",
       "</style>\n",
       "<table border=\"1\" class=\"dataframe\">\n",
       "  <thead>\n",
       "    <tr style=\"text-align: right;\">\n",
       "      <th></th>\n",
       "      <th>query</th>\n",
       "      <th>response (before)</th>\n",
       "      <th>response (after)</th>\n",
       "      <th>rewards (before)</th>\n",
       "      <th>rewards (after)</th>\n",
       "    </tr>\n",
       "  </thead>\n",
       "  <tbody>\n",
       "    <tr>\n",
       "      <th>0</th>\n",
       "      <td>Well I guess I know</td>\n",
       "      <td>that Cantor may be an</td>\n",
       "      <td>..but I loved it</td>\n",
       "      <td>0.230196</td>\n",
       "      <td>2.281557</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>1</th>\n",
       "      <td>This is an excellent,</td>\n",
       "      <td>direct-to-video film with typical</td>\n",
       "      <td>enjoyable movie.&lt;|endoftext|&gt;</td>\n",
       "      <td>2.846593</td>\n",
       "      <td>2.840860</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>2</th>\n",
       "      <td>Now, I</td>\n",
       "      <td>'ve never had the chance with James</td>\n",
       "      <td>loved the growing episode - and the</td>\n",
       "      <td>0.656194</td>\n",
       "      <td>2.525894</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>3</th>\n",
       "      <td>We tend</td>\n",
       "      <td>not to see Arthur</td>\n",
       "      <td>to like this very</td>\n",
       "      <td>-0.280880</td>\n",
       "      <td>2.183822</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>4</th>\n",
       "      <td>The proverb \"Never judge a book</td>\n",
       "      <td>by the cover\" has caught on. After glancing t...</td>\n",
       "      <td>with high compliments, but it is recommended ...</td>\n",
       "      <td>0.274649</td>\n",
       "      <td>2.065951</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>5</th>\n",
       "      <td>I've never understood</td>\n",
       "      <td>why so many artsmen,</td>\n",
       "      <td>this film but it's delightful</td>\n",
       "      <td>0.835574</td>\n",
       "      <td>2.782384</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>6</th>\n",
       "      <td>Hugh (Ed Harris) is</td>\n",
       "      <td>an acclaimed \"hero\" and his fian</td>\n",
       "      <td>a wonderful actor who is a good adaptation</td>\n",
       "      <td>1.580167</td>\n",
       "      <td>2.602940</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>7</th>\n",
       "      <td>This particular Joe McDoakes</td>\n",
       "      <td>' episode brought all the wrong bits and</td>\n",
       "      <td>movie is really a great movie. It</td>\n",
       "      <td>0.870956</td>\n",
       "      <td>2.795245</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>8</th>\n",
       "      <td>Sisters In</td>\n",
       "      <td>Vrooms 8.23, I signed up for all of the</td>\n",
       "      <td>The Universe 1: Sunny is cute, and has a cute...</td>\n",
       "      <td>1.175259</td>\n",
       "      <td>2.062330</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>9</th>\n",
       "      <td>I was very fond of this</td>\n",
       "      <td>film, it was obviously a bad idea when first ...</td>\n",
       "      <td>show, and know that I have seen it several times</td>\n",
       "      <td>1.058164</td>\n",
       "      <td>2.511273</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>10</th>\n",
       "      <td>If he wanted to be</td>\n",
       "      <td>funny, he could</td>\n",
       "      <td>a genius eventually,</td>\n",
       "      <td>-0.388943</td>\n",
       "      <td>0.405888</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>11</th>\n",
       "      <td>Thats My</td>\n",
       "      <td>Grade...&lt;br /&gt;&lt;br /&gt;Although</td>\n",
       "      <td>Way was the best movie that I watched.</td>\n",
       "      <td>-0.151680</td>\n",
       "      <td>2.473050</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>12</th>\n",
       "      <td>This is possibly the best short</td>\n",
       "      <td>film I have come across in almost two years.</td>\n",
       "      <td>film ever written. It has some very memorable...</td>\n",
       "      <td>2.511835</td>\n",
       "      <td>2.775994</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>13</th>\n",
       "      <td>Some people say this is</td>\n",
       "      <td>exactly what happens in Hollywood; where come...</td>\n",
       "      <td>a powerful film to listen to. It really captures</td>\n",
       "      <td>0.637631</td>\n",
       "      <td>2.821085</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>14</th>\n",
       "      <td>A remake of</td>\n",
       "      <td>\"The Wizard of Oz</td>\n",
       "      <td>the legendary Kingan oil</td>\n",
       "      <td>0.292409</td>\n",
       "      <td>0.434021</td>\n",
       "    </tr>\n",
       "    <tr>\n",
       "      <th>15</th>\n",
       "      <td>What a terrible</td>\n",
       "      <td>movie!&lt;|endoftext|&gt;</td>\n",
       "      <td>chopping sounded so good, I love it! We have a</td>\n",
       "      <td>-2.681461</td>\n",
       "      <td>2.340650</td>\n",
       "    </tr>\n",
       "  </tbody>\n",
       "</table>\n",
       "</div>"
      ],
      "text/plain": [
       "                              query  \\\n",
       "0               Well I guess I know   \n",
       "1             This is an excellent,   \n",
       "2                            Now, I   \n",
       "3                           We tend   \n",
       "4   The proverb \"Never judge a book   \n",
       "5             I've never understood   \n",
       "6               Hugh (Ed Harris) is   \n",
       "7      This particular Joe McDoakes   \n",
       "8                        Sisters In   \n",
       "9           I was very fond of this   \n",
       "10               If he wanted to be   \n",
       "11                         Thats My   \n",
       "12  This is possibly the best short   \n",
       "13          Some people say this is   \n",
       "14                      A remake of   \n",
       "15                  What a terrible   \n",
       "\n",
       "                                    response (before)  \\\n",
       "0                               that Cantor may be an   \n",
       "1                   direct-to-video film with typical   \n",
       "2                 've never had the chance with James   \n",
       "3                                   not to see Arthur   \n",
       "4    by the cover\" has caught on. After glancing t...   \n",
       "5                                why so many artsmen,   \n",
       "6                    an acclaimed \"hero\" and his fian   \n",
       "7            ' episode brought all the wrong bits and   \n",
       "8             Vrooms 8.23, I signed up for all of the   \n",
       "9    film, it was obviously a bad idea when first ...   \n",
       "10                                    funny, he could   \n",
       "11                       Grade...<br /><br />Although   \n",
       "12     film I have come across in almost two years.     \n",
       "13   exactly what happens in Hollywood; where come...   \n",
       "14                                  \"The Wizard of Oz   \n",
       "15                                movie!<|endoftext|>   \n",
       "\n",
       "                                     response (after)  rewards (before)  \\\n",
       "0                                    ..but I loved it          0.230196   \n",
       "1                       enjoyable movie.<|endoftext|>          2.846593   \n",
       "2                 loved the growing episode - and the          0.656194   \n",
       "3                                   to like this very         -0.280880   \n",
       "4    with high compliments, but it is recommended ...          0.274649   \n",
       "5                       this film but it's delightful          0.835574   \n",
       "6          a wonderful actor who is a good adaptation          1.580167   \n",
       "7                   movie is really a great movie. It          0.870956   \n",
       "8    The Universe 1: Sunny is cute, and has a cute...          1.175259   \n",
       "9    show, and know that I have seen it several times          1.058164   \n",
       "10                               a genius eventually,         -0.388943   \n",
       "11             Way was the best movie that I watched.         -0.151680   \n",
       "12   film ever written. It has some very memorable...          2.511835   \n",
       "13   a powerful film to listen to. It really captures          0.637631   \n",
       "14                           the legendary Kingan oil          0.292409   \n",
       "15     chopping sounded so good, I love it! We have a         -2.681461   \n",
       "\n",
       "    rewards (after)  \n",
       "0          2.281557  \n",
       "1          2.840860  \n",
       "2          2.525894  \n",
       "3          2.183822  \n",
       "4          2.065951  \n",
       "5          2.782384  \n",
       "6          2.602940  \n",
       "7          2.795245  \n",
       "8          2.062330  \n",
       "9          2.511273  \n",
       "10         0.405888  \n",
       "11         2.473050  \n",
       "12         2.775994  \n",
       "13         2.821085  \n",
       "14         0.434021  \n",
       "15         2.340650  "
      ]
     },
     "execution_count": 14,
     "metadata": {},
     "output_type": "execute_result"
    }
   ],
   "source": [
    "#### get a batch from the dataset\n",
    "bs = 16\n",
    "game_data = dict()\n",
    "dataset.set_format(\"pandas\")\n",
    "df_batch = dataset[:].sample(bs)\n",
    "game_data[\"query\"] = df_batch[\"query\"].tolist()\n",
    "query_tensors = df_batch[\"input_ids\"].tolist()\n",
    "\n",
    "response_tensors_ref, response_tensors = [], []\n",
    "\n",
    "#### get response from gpt2 and gpt2_ref\n",
    "for i in range(bs):\n",
    "    query = torch.tensor(query_tensors[i]).to(device)\n",
    "\n",
    "    gen_len = output_length_sampler()\n",
    "    query_response = ref_model.generate(\n",
    "        query.unsqueeze(0), max_new_tokens=gen_len, **gen_kwargs\n",
    "    ).squeeze()\n",
    "    response_len = len(query_response) - len(query)\n",
    "    response_tensors_ref.append(query_response[-response_len:])\n",
    "\n",
    "    query_response = model.generate(\n",
    "        query.unsqueeze(0), max_new_tokens=gen_len, **gen_kwargs\n",
    "    ).squeeze()\n",
    "    response_len = len(query_response) - len(query)\n",
    "    response_tensors.append(query_response[-response_len:])\n",
    "\n",
    "#### decode responses\n",
    "game_data[\"response (before)\"] = [\n",
    "    tokenizer.decode(response_tensors_ref[i]) for i in range(bs)\n",
    "]\n",
    "game_data[\"response (after)\"] = [\n",
    "    tokenizer.decode(response_tensors[i]) for i in range(bs)\n",
    "]\n",
    "\n",
    "#### sentiment analysis of query/response pairs before/after\n",
    "texts = [q + r for q, r in zip(game_data[\"query\"], game_data[\"response (before)\"])]\n",
    "pipe_outputs = sentiment_pipe(texts, **sent_kwargs)\n",
    "positive_scores = [\n",
    "    item[\"score\"]\n",
    "    for output in pipe_outputs\n",
    "    for item in output\n",
    "    if item[\"label\"] == \"POSITIVE\"\n",
    "]\n",
    "game_data[\"rewards (before)\"] = positive_scores\n",
    "\n",
    "texts = [q + r for q, r in zip(game_data[\"query\"], game_data[\"response (after)\"])]\n",
    "pipe_outputs = sentiment_pipe(texts, **sent_kwargs)\n",
    "positive_scores = [\n",
    "    item[\"score\"]\n",
    "    for output in pipe_outputs\n",
    "    for item in output\n",
    "    if item[\"label\"] == \"POSITIVE\"\n",
    "]\n",
    "game_data[\"rewards (after)\"] = positive_scores\n",
    "\n",
    "# store results in a dataframe\n",
    "df_results = pd.DataFrame(game_data)\n",
    "df_results"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "通过观察生成序列的奖励均值/中位数，我们发现了显著的差异。"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 15,
   "metadata": {},
   "outputs": [
    {
     "name": "stdout",
     "output_type": "stream",
     "text": [
      "mean:\n"
     ]
    },
    {
     "data": {
      "text/plain": [
       "rewards (before)    0.591666\n",
       "rewards (after)     2.243934\n",
       "dtype: float64"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    },
    {
     "name": "stdout",
     "output_type": "stream",
     "text": [
      "\n",
      "median:\n"
     ]
    },
    {
     "data": {
      "text/plain": [
       "rewards (before)    0.646912\n",
       "rewards (after)     2.492161\n",
       "dtype: float64"
      ]
     },
     "metadata": {},
     "output_type": "display_data"
    }
   ],
   "source": [
    "print(\"mean:\")\n",
    "display(df_results[[\"rewards (before)\", \"rewards (after)\"]].mean())\n",
    "print()\n",
    "print(\"median:\")\n",
    "display(df_results[[\"rewards (before)\", \"rewards (after)\"]].median())"
   ]
  },
  {
   "cell_type": "markdown",
   "metadata": {},
   "source": [
    "## 保存模型  \n",
    "最后，我们保存模型以供后续使用。"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": 16,
   "metadata": {},
   "outputs": [
    {
     "data": {
      "text/plain": [
       "('model/gpt2-imdb-pos-v2/tokenizer_config.json',\n",
       " 'model/gpt2-imdb-pos-v2/special_tokens_map.json',\n",
       " 'model/gpt2-imdb-pos-v2/vocab.json',\n",
       " 'model/gpt2-imdb-pos-v2/merges.txt',\n",
       " 'model/gpt2-imdb-pos-v2/added_tokens.json',\n",
       " 'model/gpt2-imdb-pos-v2/tokenizer.json')"
      ]
     },
     "execution_count": 16,
     "metadata": {},
     "output_type": "execute_result"
    }
   ],
   "source": [
    "model.save_pretrained(\"model/gpt2-imdb-pos-v2\")\n",
    "tokenizer.save_pretrained(\"model/gpt2-imdb-pos-v2\")"
   ]
  }
 ],
 "metadata": {
  "kernelspec": {
   "display_name": "gui",
   "language": "python",
   "name": "python3"
  },
  "language_info": {
   "codemirror_mode": {
    "name": "ipython",
    "version": 3
   },
   "file_extension": ".py",
   "mimetype": "text/x-python",
   "name": "python",
   "nbconvert_exporter": "python",
   "pygments_lexer": "ipython3",
   "version": "3.11.11"
  }
 },
 "nbformat": 4,
 "nbformat_minor": 4
}